Agent-guided de novo nanobody design: 46 of 116 candidates confirmed by SPR, with a best KD of 0.66 nM
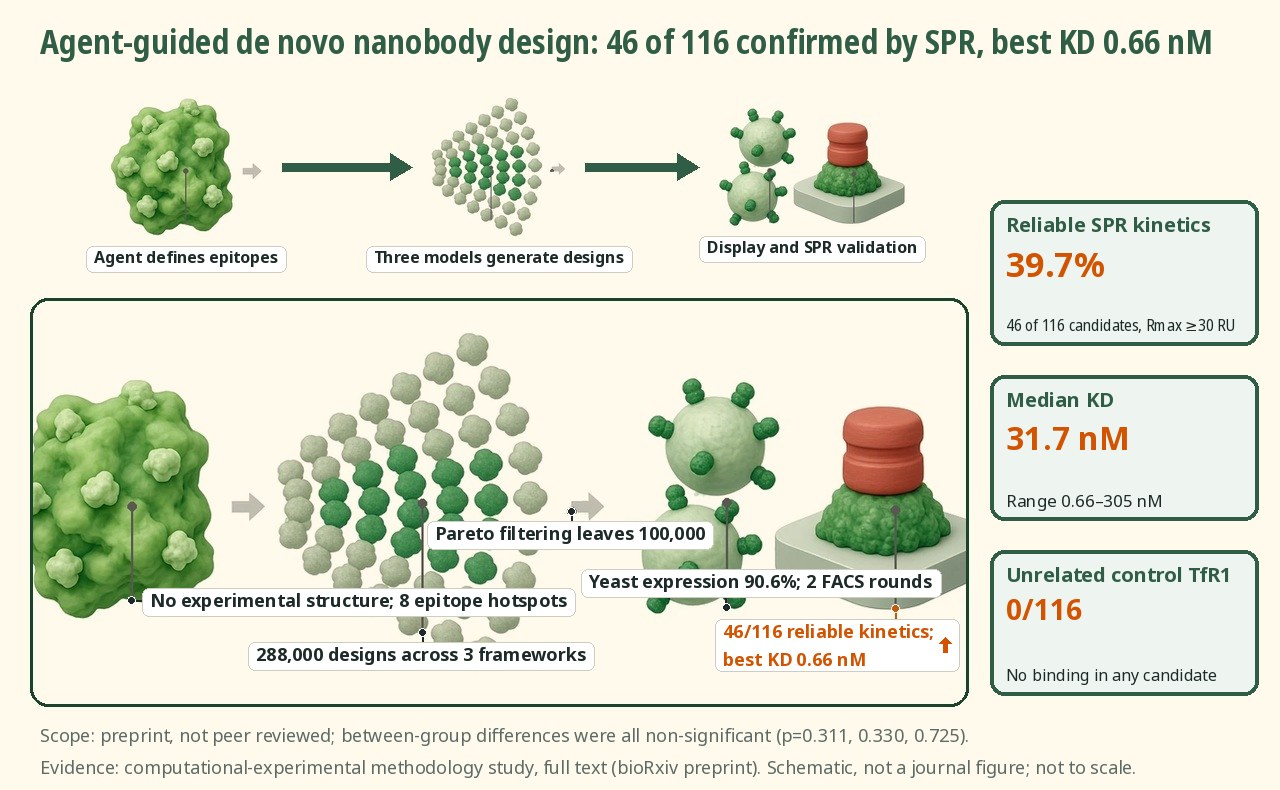
Against a novel DSRCT target with no structure and no existing antibodies, Zhao et al. generated 288,000 de novo nanobody designs; of 116 candidates characterized by SPR, 46 (39.7%) yielded reliable kinetics, with a best KD of 0.66 nM.
Preprint. This study has not yet been peer reviewed; findings may change.
Against a novel desmoplastic small round cell tumour target with no structure and no existing antibodies, agent-guided de novo design generated 288,000 nanobody designs covering 8 epitope hotspots. After Pareto filtering, 100,000 entered yeast surface display, and after two rounds of sorting 116 went to surface plasmon resonance, where 46 (39.7%) yielded reliable kinetics with equilibrium dissociation constants of 0.66 to 305 nM and a median of 31.7 nM. The paper is a preprint that has not been peer reviewed.
Background and open questions
Monoclonal antibodies are already the mainstay of biologics, and nanobodies (VHHs) extend the accessible formats thanks to good solubility, high stability and ease of engineering. But conventional discovery routes — animal immunization, phage display, synthetic libraries — restrict the accessible sequence space, and the literature the authors cite indicates that one discovery round typically takes 6–12 months and can hardly specify the epitope in advance.
Machine learning has brought structure prediction and de novo design tools, but reported experimental hit rates range from 0.1% to 39%, with inconsistent definitions of a hit and differing target difficulty, making direct comparison hard. In this bioRxiv preprint (not peer reviewed), Zhao et al. chain these tools into an agent-guided pipeline and run a first round of validation on a novel cancer target.
Study design
The target came from RNA sequencing of 47 surgical specimens of desmoplastic small round cell tumour (DSRCT) at Memorial Sloan Kettering Cancer Center: differential expression against 5 healthy peritoneal tissues, then restriction to genes upregulated by EWSR1::WT1, predicted to be cell surface localized, and without appreciable expression in GTEx normal tissues, with the most strongly upregulated gene selected. The target has neither an experimentally solved structure nor any publicly available antibody information, so design had to start from sequence alone.
The workflow has four steps: a hotspot recommendation agent (based on Claude Sonnet 4, integrating outputs from tools such as IEDB, PFAM and surface accessibility) proposes 8 epitope hotspots; RFantibody, IgGM and mBER generate designs on predicted structures from four folding methods; a candidate selection agent performs Pareto filtering after multi-metric scoring; and the results are validated by yeast surface display plus FACS plus SPR. The study was not powered for any between-group comparison.
Key results
116 reach SPR after two rounds of enrichment
Design parameters were varied combinatorially: 8 computationally identified epitope hotspots, 3 nanobody frameworks and CDR III lengths of 4 to 13 amino acids, all sampled across three generative models, giving 288,000 designs; the candidate selection agent then applied multi-objective Pareto filtering, leaving 100,000 for yeast surface display screening. The yeast library had a VHH expression rate of 90.6%, and after 2 rounds of FACS enrichment 116 candidates were picked by mean fluorescence intensity for SPR.
46 yield reliable kinetics
All 116 candidates expressed successfully, with the Results reporting a median yield of 184 mg/L (34.5–200 mg/L) and no binding to the unrelated antigen transferrin receptor (TfR1). Of these, 46 (39.7%) gave reliable kinetic fits with Rmax≥30 RU, with KD from 0.66 nM to 305 nM and a median of 31.7 nM; the best candidate, PRJ266_044, had a KD of 0.66 nM and the runner-up, PRJ266_080, 2.3 nM. A further 29 candidates gave detectable but low-amplitude responses (Rmax<30 RU), and the authors state explicitly that their KD values can only be treated as tentative estimates.
Framework determines success
Among the 46 high-signal binders, only two of the three frameworks produced any, and the distribution was heavily skewed: framework B accounted for 45. Both IgGM and mBER contributed, with IgGM producing more and a lower median KD (n=33, median 28.0 nM versus n=13 and 43.9 nM for mBER), though the difference was not significant (p=0.311). RFantibody produced three binders with KD of 0.13, 0.62 and 5.5 nM, but with Rmax of only 11.1–16.4 RU, all below the threshold.
Hotspots can be recovered but are not epitopes
All eight hotspot condition groups recovered SPR-confirmed binders, but the authors stress that the true binding interface need not coincide with the conditioning hotspot; median KD by group ranged from 10.3 nM for hotspot G to 43.9 nM for hotspot B, with no significant difference between groups (p=0.725). Median affinity across the five predicted structures was 26.5–47.5 nM (p=0.330), and the authors note that splitting 46 binders across five groups leaves the comparison severely underpowered.
Mechanistic interpretation
Demonstrated in the paper: What the experiments directly support is the recoverability of the workflow's steps: Boltz-2, co-folding from sequence alone, concentrated the designed CDR contacts near the conditioning hotspots, showing that epitope preference is encoded in sequence and can be recovered by independent structure prediction; the authors also note that Boltz-2 and the design models share PDB training data, so common bias cannot be excluded. Pairwise TM-scores among the five predicted structures all exceeded 0.5, with AlphaFold2 the most divergent (0.62–0.66).
Hotspot recommendation was separately evaluated on SAbDab complexes: a test set clustered at 70% identity with n=320, plus a held-out set of n=76; the agent proposed 5 non-overlapping 10-amino-acid regions per antigen, with overlap with any true epitope residue counted as a hit, giving top-5 accuracy of about 80% on the held-out set.
Author hypotheses: The authors suggest that hotspot B together with hotspots F and G may form parts of a discontinuous epitope, which could explain overlapping contact signals across those regions; they also regard the enrichment of low-KD binders in these three groups as hypothesis-generating only, given the small group sizes. The overwhelming share of framework B is interpreted as framework properties potentially determining whether a computational design translates into a strong binder.
Limitations and uncertainties
- The authors list two limitations themselves: biophysical property assessment is limited, currently relying on computational metrics such as Boltz-2 co-folding and MochiBind affinity estimation, which may not capture conformational stability or dynamic instability; and scaffold diversity is limited, with the workflow using only the three generative methods RFantibody, IgGM and mBER, which may restrict exploration of other scaffold classes.
- The level of evidence is limited: SPR can confirm binding but cannot determine the epitope, and the authors call for experimental epitope mapping; the between-group affinity comparisons (p=0.311 for generative model, p=0.330 for structural method, p=0.725 for hotspot) were all non-significant and underpowered and cannot be used to select methods.
- This is a bioRxiv preprint, not peer reviewed, and it completes only one design-build-test round; developability characterization such as thermal stability and polyreactivity and cell-level validation have not been done, and the affinities of the 29 low-signal candidates need orthogonal confirmation.
Clinical and industry implications
If confirmed by further cycles and peer review, this pipeline shows that for targets without an experimental structure or any existing antibody, agent-defined epitopes plus multi-model de novo design can yield nanomolar to sub-nanomolar nanobodies in the first round, shifting screening scale from biological selection in conventional libraries to computational design with specifiable epitopes.
The practical lesson for teams is to treat framework and generative method as design variables to diversify deliberately and to feed experimental data back into training target-specific models; the authors have planned cell validation and developability characterization for subsequent design-build-test-learn cycles.
Numbers are as reported by the authors. Corrections: contact@
Related science
MedGemma brings open medical vision-language models to Gemma 3
One open-weight model family, medically tuned from Gemma 3, spanning medical images and text
Rentosertib phase 2a: 21/54 aging-clock comparisons significant
A cell cluster with red-marked molecules, showing proteomic aging-related changes
511 AI antibodies benchmarked: only 9.8–13.8% beat the control in Challenge 2
Many antibodies pointing at a green antigen, with the best binder in red
One email, with links to every paper. Reports and custom landscapes: contact@inlightbio.com.
Opens your email app with a pre-filled request; we add you by hand. Free, unsubscribe any time.