AIntibody blinded benchmark: 511 AI antibodies reach a best of 95 pM in affinity maturation, with uneven performance across tasks
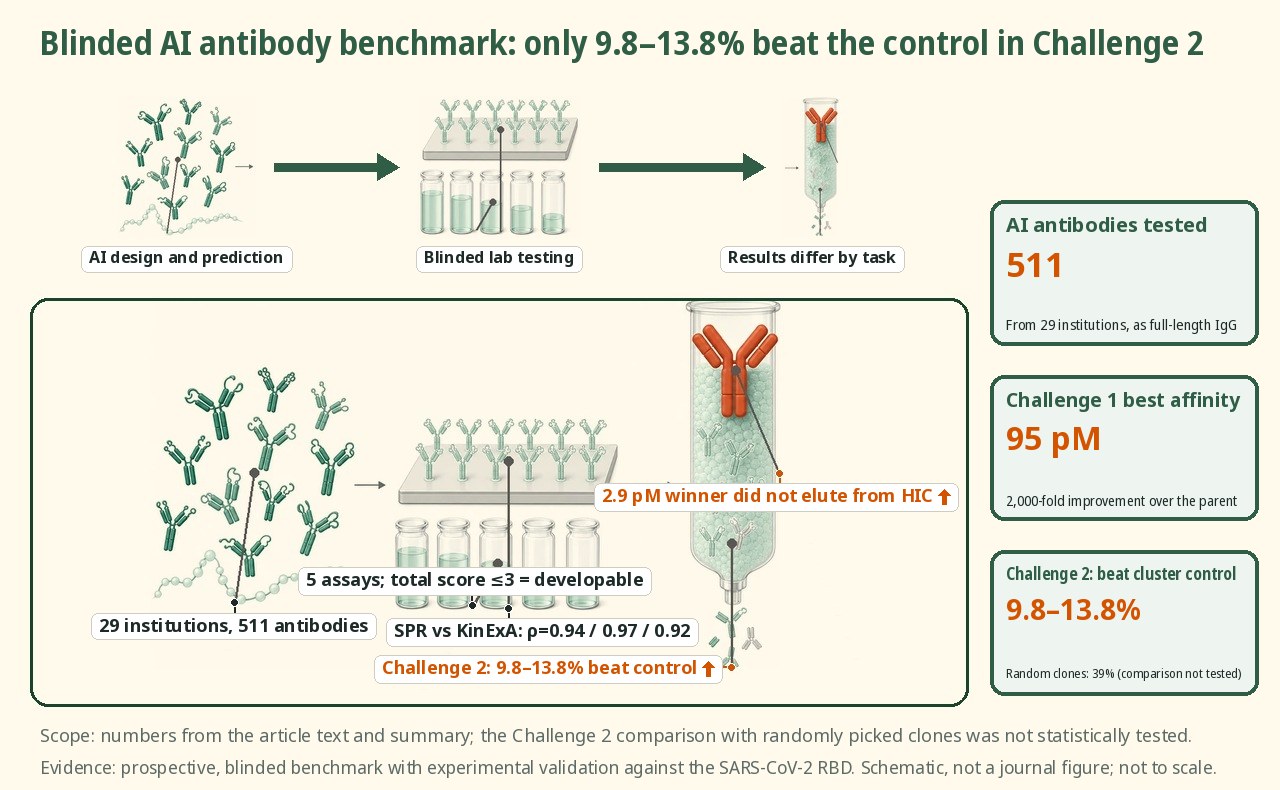
511 AI-designed or AI-predicted antibodies from 29 institutions were experimentally validated in a blinded benchmark: the best in Challenge 1 reached 95 pM (a 2,000-fold improvement over the parent), while in Challenge 2 only 9.8–13.8% of submissions had higher affinity than the cluster control.
In the AIntibody blinded benchmark, 511 AI-designed or AI-predicted antibodies from 29 institutions were synthesized and tested under uniform conditions against the SARS-CoV-2 RBD. Challenge 1 (affinity maturation) drew 165 submissions from 25 institutions, with a best of 95 pM, a 2,000-fold improvement over the parent. In Challenge 2 (within-cluster ranking), only 9.8–13.8% of submissions had higher affinity than the cluster control, versus 39% for randomly picked clones, and only WashU reached 50%. The Challenge 3 winner reached 2.9 pM but did not elute from the HIC column. ProBioGen's consensus sequence, which used no machine learning, ranked third at 540 pM with no developability issues.
Background and open questions
Most performance assessments of computational antibody design rely on retrospective analysis without new experiments, with limited external validation, making true capability hard to judge; the problem is sharper as methods proliferate in preprints and technical reports. The structure prediction field established common standards through CASP's prospective blinded assessments, but the antibody field has lacked an equivalent benchmark.
Antibody engineering requires multi-parameter optimization: beyond affinity there is developability, including expression, Tm, polyreactivity and aggregation, and improving one property without harming others is hard. Amino acid sequences do not reveal function to the human eye, and the diverse experimental data needed for affinity prediction are scarce and scattered. This study anchors a prospective blinded benchmark to experimentally measured affinity and developability.
Study design
AIntibody is a prospective blinded challenge against the SARS-CoV-2 RBD that tested 511 AI-designed or AI-predicted antibodies from 29 institutions across three tasks: affinity maturation based on first-round sequencing, affinity ranking within three HCDR3 clusters, and CDR design beyond the complete selection output. Sequences were expressed as full-length IgG and tested by an independent laboratory; the study was not powered for between-group comparisons.
Affinity was measured by HT-SPR and KinExA. Developability used five assays, AC-SINS, BVP, HIC, Tm and Tagg, each scored 0 (pass), 1 (questionable) or 2 (fail), with thresholds calibrated to clinical-stage antibodies per Jain et al., and a total of ≤3 counted as developable. Rank correlations: SPR versus single-point KinExA ρ=0.94, single-point versus standard KinExA ρ=0.97, standard KinExA versus SPR ρ=0.92; correlations for absolute affinity were weaker, and KinExA values were generally higher.
Key results
Challenge 1: affinity maturation
Challenge 1 asked participants to mature a parental antibody without changing HCDR3 or the framework. Among 165 submissions from 25 institutions, 71.5% bound the RBD, 3.0% reached sub-nanomolar affinity and only 1 (0.6%) reached sub-100 pM; 86.1% passed developability and 63.0% were developable binders. Aureka's winning sequence reached 95 pM, a 2,000-fold improvement over the parent.
Comparison with experimental antibodies and the consensus sequence
The best AI SPR affinity was 340 pM versus 517 pM for the best experimental antibody; by KinExA the top five experimental antibodies spanned 113–1,230 pM and the top five AI antibodies 95–984 pM, with overlapping confidence intervals, which the paper judged statistically indistinguishable. ProBioGen's consensus sequence, built without machine learning, was identical to the library consensus across all six CDRs, ranked third at 540 pM by KinExA with no developability issues, ahead of most AI designs.
Challenge 2: within-cluster ranking
In the three clusters, 10.3%, 13.8% and 9.8% of submissions had higher affinity than the cluster control (the most abundant clone), so only 9.8–13.8% across all AI submissions; among winners the figure was 11–50%, versus 39% for randomly picked clones. Apart from WashU (50% versus 39%), every AI prediction strategy performed worse than random picking. The paper reports no statistical test for this comparison.
Best prediction per cluster
For 27F the best was 9.2 pM, a 4.0-fold improvement over the cluster control (36.6 pM); for 47F it was 50 pM versus 378 pM for the control, a 7.6-fold improvement; 28F improved only 1.8-fold (101 versus 177 pM). For 28F, 41.4% of submissions were disqualified for poor developability, while 47F had a 100% pass rate, so developability correlated strongly with HCDR3 cluster.
Challenge 3: design beyond the library
Challenge 3 provided affinities for 142 antibodies. The best experimental antibody was 9.2 pM by KinExA; two submissions were stronger at 2.9 and 3.1 pM, four more were comparable (8.7–9.6 pM), and only one (1.2% of the total) met the developability criterion (score ≤3). The winning 2.9 pM antibody did not elute from the HIC column and would most likely be dropped under conventional therapeutic criteria, yet won because the composite score allows a single failure to be offset.
Mechanistic interpretation
Demonstrated in the paper: High-affinity antibodies showed specific motifs (a tyrosine at LCDR1 position 6 and a tryptophan at LCDR3 position 8), and some AI algorithms incorporated these substitutions given the data available. Aureka's winning sequence differed from the parent by 19 substitutions and from the experimental dataset by at least 12; the top Challenge 3 submissions all reused HCDR3s already present in the experimental data.
The winning method category varied by task: Aureka (a PLM plus structure) won Challenge 1, Xencor (a PLM) won Challenge 3, and 28F was tied between WashU and Xencor; the paper notes wide variation within categories, so these reflect overall trends only, not controlled comparisons.
Author hypotheses: The authors suggest that success in within-cluster ranking may depend on the specifics of the local epitope or cluster rather than on method category, and that PLM-based methods may be more useful for generating novel sequences outside the library. They also argue that the winners' reliance on HCDR3 motifs already present in the data leaves it uncertain whether they transfer to data-poor settings, and on that basis advocate matching methods to tasks.
Limitations and uncertainties
- Generalizability: only one antigen (the SARS-CoV-2 RBD) with deliberately rich data; the authors describe the results as an upper bound on current computational capability for this class of target rather than a guide to other antigens; Challenges 2 and 3 also supplied affinity data, which early discovery usually lacks.
- Blinding and participation: the first round was organized by the same consortium reporting the results, with blinding guaranteed by organizer integrity rather than informatic means, and several well-known groups did not take part.
- Endpoints and statistics: the Challenge 2 comparison with the 39% random rate was not tested; KinExA was run only on the strongest subset (just 8 AI submissions in Challenge 1); and the composite score allows a single failure to be offset.
- Reporting discrepancy: the legend for Fig. 3d gives 5.2% for 28F while the main text gives 13.8%.
Clinical and industry implications
Where a target antigen already has deep sequencing data, tasks such as affinity maturation could use the best-performing AI methods to shorten experimental cycles; the paper estimates that if Aureka's model applies broadly it could save 2–3 weeks, and suggests that synthesizing and testing 10–20 designs is enough to find useful high-affinity variants. The machine-learning-free consensus sequence provides a baseline that future methods must at least surpass.
If future benchmarks adopt hard go/no-go criteria, scoring will come closer to the practical requirements of therapeutic development; the authors plan to reassess in the next round in 2026 using unknown targets and no affinity data.
Numbers are as reported by the authors. Corrections: contact@
Related science
MedGemma brings open medical vision-language models to Gemma 3
One open-weight model family, medically tuned from Gemma 3, spanning medical images and text
Rentosertib phase 2a: 21/54 aging-clock comparisons significant
A cell cluster with red-marked molecules, showing proteomic aging-related changes
NISE zero-shot design of drug-binding proteins: APEX affinity of 80 pM
A green designed protein enclosing a red small-molecule drug
One email, with links to every paper. Reports and custom landscapes: contact@inlightbio.com.
Opens your email app with a pre-filled request; we add you by hand. Free, unsubscribe any time.